Voice is one of the most natural ways for kids to learn, explore, and show what they know. Yet today's automatic speech recognition (ASR) technology hardly understands them.
This work set out to close that gap. With support from the Gates Foundation, DrivenData assembled the largest dataset of transcribed English child speech for developing open ASR models, then ran the On Top of Pasketti Challenge, in which experts from around the world competed to develop the best ASR models for kids' speech. The challenge ran two tracks to develop two kinds of transcription models:
- A word-level model, which captures which words a child said and supports use cases such as reading and reasoning assessments
- A phonetic model, which captures exactly how words were spoken and supports use cases like screening for atypical speech development.
Challenge Results
Over 828 participants submitted more than 2,100 solutions across both tracks. In the Word Track, top solvers cut the error rate of the best existing children's speech model by more than 50%, converging on fine-tuned Qwen3-ASR-1.7B. In the Phonetic Track, winners improved 49% over the reference solution using WavLM-based ensembles.
Meet the winning teams and read about their approaches
Open Models
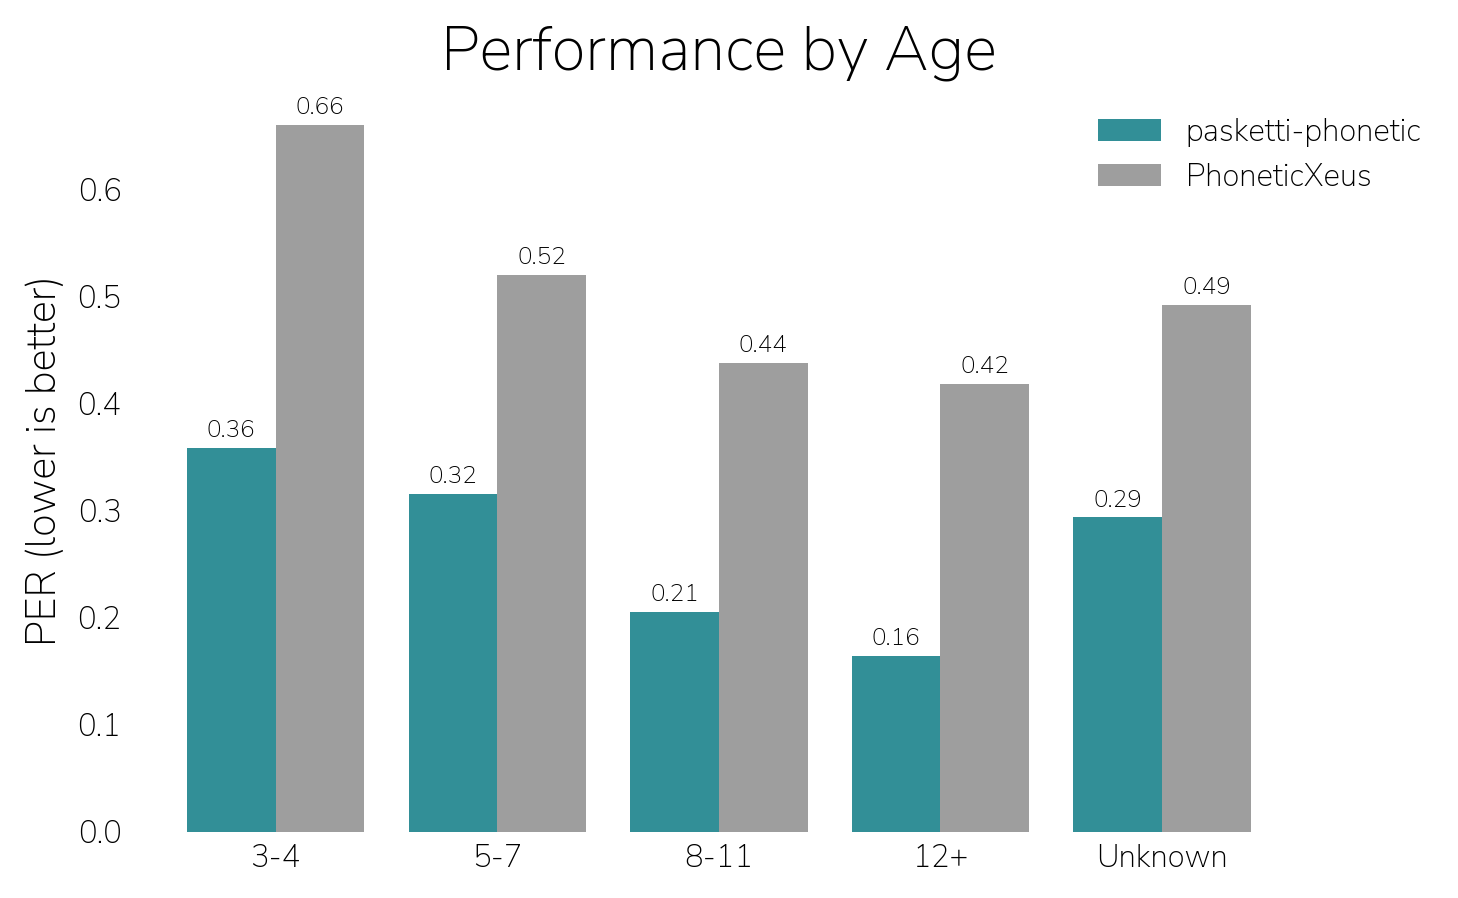
DrivenData retrained the winning approaches on more data and released them as two open models, pasketti-word and pasketti-phonetic, whose performance by age is shown below.
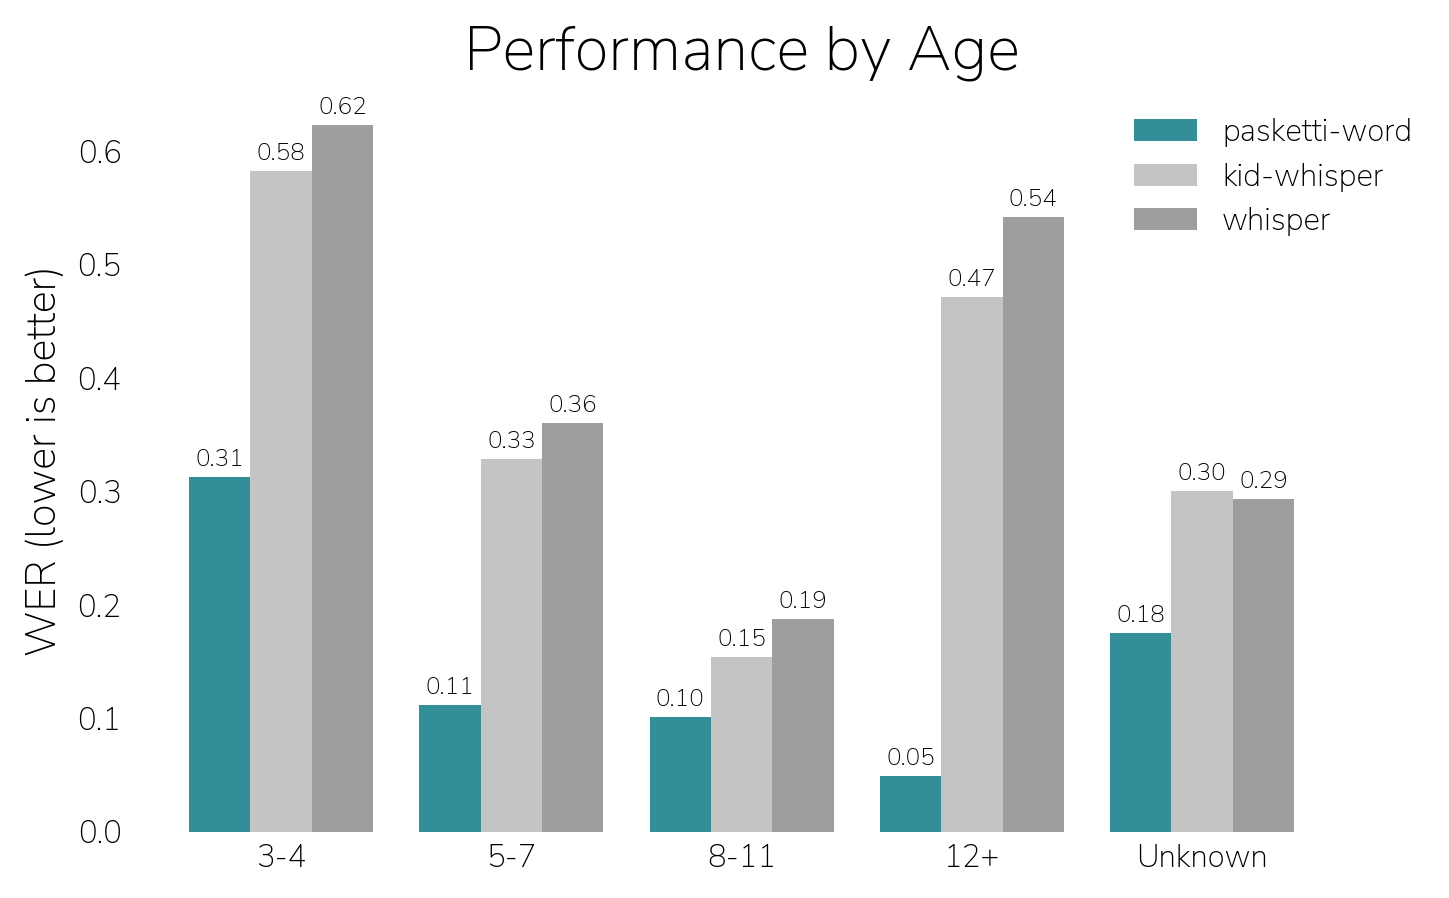
Left: word error rate (roughly the share of words a model gets wrong) for the retrained word model, compared with OpenAI Whisper and KidWhisper.
Right: phone error rate (PER, the share of speech sounds a model gets wrong) for the retrained phonetic model, compared with PhoneticXeus, a leading open phone recognizer.
OpenAI Whisper performs poorly on the 12+ age group, which comes from particularly challenging recordings of individual speech sounds. Unknown reflects recordings without age information. For how the models were evaluated, and for performance by speech pathology, race, setting, sex, and source corpus, see the Pasketti model cards on Hugging Face.
The competitions
Phonetic Track
Develop automatic speech recognition models that produce phone-level transcriptions of children’s speech in IPA. #education
Word Track
Develop automatic speech recognition models that produce word-level transcriptions of children’s speech. #education